Publications
2026
- ICLR 2026FastCar: Cache Attentive Replay for Fast Auto-Regressive Video Generation on the Edge
- AAAI 2026OIDA-QA: A Multimodal Benchmark for Analyzing the Opioid Industry Documents Archive
- CVPR 2026DiffGraph: An Automated Agent-driven Model Merging Framework for In-the-Wild Text-to-Image Generation
-
-
- arXiv preprint arXiv:2601.04589, 2026MiLDEdit: Reasoning-Based Multi-Layer Design Document Editing
2025
- EMNLP 2025Commit: Coordinated instruction tuning for multimodal large language models
- WACV 2025ARTIST: Improving the Generation of Text-rich Images with Disentangled Diffusion Models
- WACV 2025Differential privacy mechanisms in neural tangent kernel regression
- Submitted to ACL 2025A multi-llm debiasing framework
- ICLR 2025Imagefolder: Autoregressive image generation with folded tokens
- ICLR 2025LoRA-Contextualizing Adaptation of Large Multimodal Models for Long Document Understanding
- TMLR, 2025Personalization of large language models: A survey
-
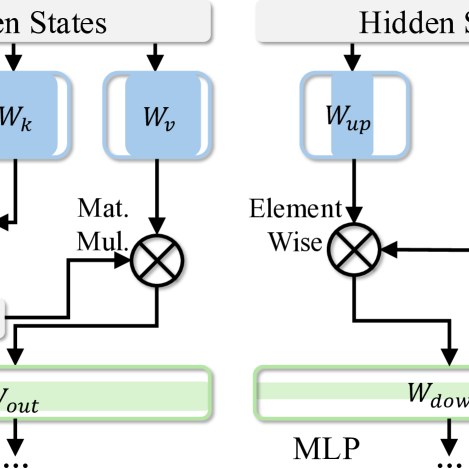
- AAAI 2025LazyDiT: Lazy Learning for the Acceleration of Diffusion Transformers
- CVPR 2025MegaSynth: Scaling Up 3D Scene Reconstruction with Synthesized Data
- ICCV 2025Refer to Anything with Vision-Language Prompts
- ICCV 2025DiffIP: Representation Fingerprints for Robust IP Protection of Diffusion Models
- ICCV 2025Multimodal LLMs as Customized Reward Models for Text-to-Image Generation
-
- ACL 2025From Selection to Generation: A Survey of LLM-based Active Learning
- Submitted to NeurIPS 2025Efficient Reasoning with Hidden Thinking
- Submitted to NeurIPS 2025ADOPT: A Multimodal Framework for Document Understanding and Generation
- Submitted to NeurIPS 2025DraftAttention: Fast Video Diffusion via Low-Resolution Attention Guidance
- Submitted to NeurIPS 2025MENTOR: Efficient Multimodal-Conditioned Tuning for Autoregressive Vision Generation Models
- TMLR, 2025From Preferences to Prejudice: The Role of Alignment Tuning in Shaping Social Bias in Video Diffusion Models
- NeurIPS 2025R-KV: Redundancy-aware KV Cache Compression for Reasoning Models
- Submitted to NeurIPS 2025ADOPD-Instruct: A Large-Scale Multimodal Dataset for Document Editing
- ACL 2025Metal: A multi-agent framework for chart generation with test-time scaling
- Submitted to ICCV 2025Robust Latent Matters: Boosting Image Generation with Sampling Error Synthesis
- CVPR 2025QuartDepth: Post-Training Quantization for Real-Time Depth Estimation on the Edge
- 2025Towards Visual Text Grounding of Multimodal Large Language Model
-
- arXiv preprint arXiv:2512.12487, 2025More Than the Final Answer: Improving Visual Extraction and Logical Consistency in Vision-Language Models
2024
- 2024Improving a Named Entity Recognizer Trained on Noisy Data with a Few Clean Instances
-
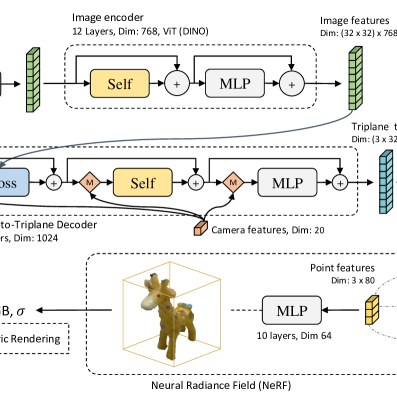
- CVPR 2024Customization assistant for text-to-image generation
- ACL 2024Selective reflection-tuning: Student-selected data recycling for llm instruction-tuning
- ICLR 2024SOHES: Self-supervised open-world hierarchical entity segmentation
- arXiv preprint arXiv:2405.03251, 2024Exploring the frontiers of softmax: Provable optimization, applications in diffusion model, and beyond
- COLING 2024DocScript: Document-Level Script Event Prediction
- CVPR 2024Trins: Towards multimodal language models that can read
- arXiv preprint arXiv:2406.09305, 2024Toffee: Efficient million-scale dataset construction for subject-driven text-to-image generation
- CVPR 2024DocSynthv2: A Practical Autoregressive Modeling for Document Generation
- NAACL 2024Self-Cleaning: Improving a Named Entity Recognizer Trained on Noisy Data with a Few Clean Instances
- ICML 2024Category-aware active domain adaptation
- arXiv preprint arXiv:2407.19185, 2024Llava-read: Enhancing reading ability of multimodal language models
- arXiv preprint arXiv:2408.14594, 2024Mmr: Evaluating reading ability of large multimodal models
- EMNLP 2024TextLap: Customizing Language Models for Text-to-Layout Planning
- EMNLP 2024Advancing Vision-Language Models with Adapter Ensemble Strategies
- arXiv preprint arXiv:2410.16400, 2024VipAct: Visual-perception enhancement via specialized vlm agent collaboration and tool-use
-
- arXiv preprint arXiv:2412.01762, 2024XQ-GAN: An Open-source Image Tokenization Framework for Autoregressive Generation
-
- arXiv preprint arXiv:2412.10533, 2024SUGAR: Subject-Driven Video Customization in a Zero-Shot Manner
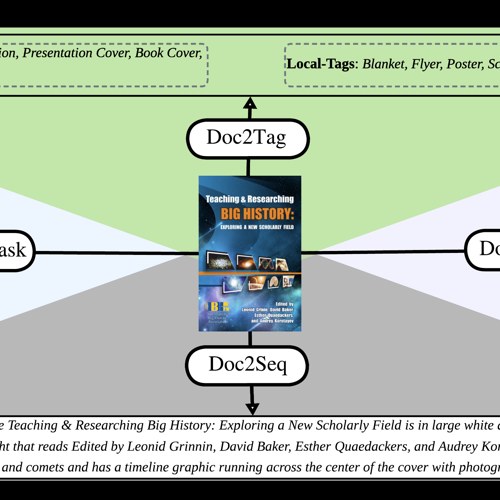
2023
- ICCV 2023High-Quality Entity Segmentation
- WACV 2023LayerDoc: layer-wise extraction of spatial hierarchical structure in visually-rich documents
- ACL 2023A critical analysis of out-of-distribution detection for document understanding
- ACL 2023Learning the visualness of text using large vision-language models
- NeurIPS 2023AIMS: all-inclusive multi-level segmentation for anything
- AAAI 2023Docedit: language-guided document editing
- NeurIPS Workshop 2023Llavar: Enhanced visual instruction tuning for text-rich image understanding
- EMNLP 2023A critical analysis of document out-of-distribution detection
- NeurIPS Workshop 2023Reflection-tuning: Data recycling improves llm instruction-tuning
2022
- AAAI 2022UNISON: Unpaired cross-lingual image captioning
- T-PAMI, 2022 JournalOpen world entity segmentation
- CVPR 2022Open-vocabulary instance segmentation via robust cross-modal pseudo-labeling
- CVPR 2022Towards language-free training for text-to-image generation
- ECCV 2022Ca-ssl: Class-agnostic semi-supervised learning for detection and segmentation
- Big Data 2022User-entity differential privacy in learning natural language models
- AAAI 2022Tigan: Text-based interactive image generation and manipulation
- ACM Web 2022Fedkc: Federated knowledge composition for multilingual natural language understanding
- ACL 2022Learning adaptive axis attentions in fine-tuning: Beyond fixed sparse attention patterns
- CVPR 2022Ei-clip: Entity-aware interventional contrastive learning for e-commerce cross-modal retrieval
- NNACL 2022Doctime: A document-level temporal dependency graph parser
- ECCV 2022Meta spatio-temporal debiasing for video scene graph generation
- INTERSPEECH 2022DocLayoutTTS: Dataset and Baselines for Layout-informed Document-level Neural Speech Synthesis.
- ECCV 2022Improving the reliability for confidence estimation
- NeurIPS, 2022Delving into out-of-distribution detection with vision-language representations
- EMNLP 2022MGDoc: Pre-training with multi-granular hierarchy for document image understanding
2021
- NAACL 2021Towards interpreting and mitigating shortcut learning behavior of NLU models
- CVPR 2021Multi-scale aligned distillation for low-resolution detection
- CVPR 2021Selfdoc: Self-supervised document representation learning
- CVPR 2021Exploiting semantic embedding and visual feature for facial action unit detection
-
2020
- PESGM 2020 Best PaperResilient load restoration in microgrids considering mobile energy storage fleets: A deep reinforcement learning approach
- ECCV 2020Finding it at another side: A viewpoint-adapted matching encoder for change captioning
- 2020Self-supervised relationship probing
2019
- ICCV 2019Unpaired Image Captioning via Scene Graph Alignments
- CVPR 2019Scene graph generation with external knowledge and image reconstruction
- ACM MM 2019Watch It Twice: Video Captioning with a Refocused Video Encoder
2018
-
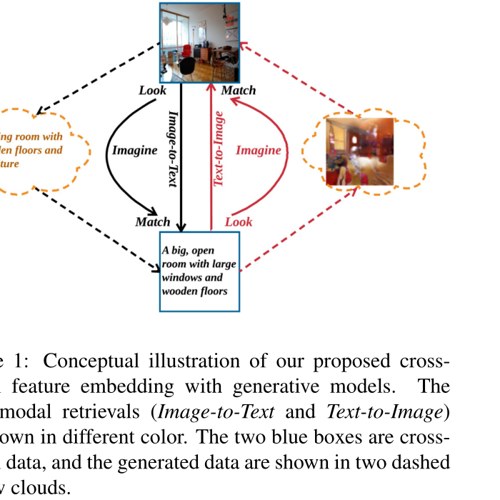 CVPR 2018 SpotlightLook, Imagine and Match: Improving Textual-Visual Cross-Modal Retrieval with Generative Models
-
- Neurocomputing, 2018Video Captioning with Boundary-aware Hierarchical Language Decoding and Joint Video Prediction
- ECCV 2018Unpaired image captioning by language pivoting
- TRECVID 2018NTU ROSE Lab at TRECVID 2018: Ad-hoc Video Search and Video to Text.
2017
- ICCV 2017An empirical study of language cnn for image captioning
2014
- Journal of University of Chinese Academy of Sciences, 2014HJ-1C real-time image processing technology based on GPU
2013
- Microelectronics & Computer, 2013Research of RS Decoding Technology Based on GPU
Patents
2026
- 2026 US Patent App. 18/777,186Text rendering for image generation models
- 2026 US Patent 12,524,954Generating 3D models from a single image
2025
- 2025 US Patent App. 18/347,877Efficient vision-language retrieval using structural pruning
- 2025 US Patent App. 18/493,465Generating temporal dependency graphs
- 2025 US Patent App. 18/952,023Utilizing a generative neural network to interactively create and modify digital images based on natural language feedback
- 2025 US Patent App. 18/460,747Generating 3d models from a single image
- 2025 US Patent App. 18/528,116Position-based text-to-speech model
- 2025 US Patent App. 18/472,746Generating an improved named entity recognition model using noisy data with a self-cleaning discriminator model
- 2025 US Patent App. 19/239,469Unified pretraining framework for document understanding
2024
- 2024 US Patent 11,886,815Self-supervised document representation learning
- 2024 US Patent 12,136,185Multi-scale distillation for low-resolution detection
- 2024 US Patent 12,148,119Utilizing a generative neural network to interactively create and modify digital images based on natural language feedback
- 2024 US Patent App. 17/947,737Image and semantic based table recognition
- 2024 US Patent App. 18/048,900Label induction
- 2024 US Patent App. 18/173,199Training language models and preserving privacy
- 2024 US Patent App. 18/055,752Extracting document hierarchy using a multimodal, layer-wise link prediction neural network
- 2024 US Patent 11,995,394Language-guided document editing
- 2024 US Patent App. 18/318,921TEXT-TO-IMAGE SYSTEM AND METHOD
- 2024 US Patent App. 18/339,883IDENTIFYING VISUAL TEXT USING VISION-LANGUAGE MODELS
- 2024 US Patent App. 18/328,950EFFICIENT AUGMENTATION FOR MULTIMODAL MACHINE LEARNING
2023
- 2023 US Patent 11,610,393Knowledge distillation for neural networks using multiple augmentation strategies
- 2023 US Patent 11,816,243Preserving user-entity differential privacy in natural language modeling
- 2023 US Patent App. 17/528,972Enhanced document visual question answering system via hierarchical attention
- 2023 US Patent App. 17/577,605Facilitating identification of fillable regions in a form
- 2023 US Patent App. 17/650,437Open vocabulary instance segmentation
- 2023 US Patent App. 17/740,497Adaptive sparse attention pattern
- 2023 US Patent App. 17/664,079Systems and methods for product retrieval
- 2023 US Patent App. 17/746,779Multimodal extraction across multiple granularities
- 2023 US Patent App. 17/806,097Open vocabulary instance segmentation with noise estimation and robust student
2022
- 2022 PatentGenerating scene graphs from digital images using external knowledge and image reconstruction
- 2022 US Patent App. 17/093,185Self-supervised visual-relationship probing
- 2022 US Patent App. 17/805,289Generating scene graphs from digital images using external knowledge and image reconstruction